Hacker News ReaderTop Best

GPT-6 Sol and Luna | 94

GPT-6 Sol and Luna

openai.com

GPT-6 Sol and Luna

Claude Opus 5.5 | 145

Claude Opus 5.5

Anthropic logo
anthropic.com

Introducing Claude Opus 5.5 \ Anthropic

Claude Opus 5.5 leads in agentic coding and knowledge work, and costs 40% less to run than Opus 5 on typical workloads.

'We hacked the FBI:' Hackers say they have data on all FBI employees | 25
404media.co

‘We Hacked the FBI:’ Hackers Say They Have Data on All FBI Employees

A sample of 5,000 alleged agents seen by 404 Media includes names, addresses, phone numbers, and details on FBI employees' spouses.

OpenAI GPT–6 Astra breaks Enigma message that has resisted solution since 2005 | 49

cryptocellar.org

The MVUEH Break

SAML: A Fractal of Bad Design | 11

SAML: A Fractal of Bad Design

blog.trailofbits.com

SAML: A fractal of bad design - The Trail of Bits Blog

SAML, the XML-based authentication protocol that birthed the SSO industry, is fundamentally flawed due to XML complexity, canonicalization issues, enveloped signatures, and design ossification, making it vulnerable to signature wrapping attacks and parser differentials that persist despite decades of awareness. Organizations should migrate to OpenID Connect (OIDC), which avoids these pitfalls through simpler JSON-based design, detached signatures, and agile evolution.

Claude Opus 5.5 Intelligence, Performance and Price Analysis (Max) | 16

Model intelligence, performance, and price analysis
artificialanalysis.ai

Claude Opus 5.5 (max with fallback) - Intelligence, Performance & Price Analysis | Artificial Analysis

Analysis of Anthropic's Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) and comparison to other AI models across key metrics including quality, price, performance (tokens per second & time to first token), context window & more.

Microsoft killed FoxPro in 2007. Anyway, here's FoxPro revived | 1

foxscript.org

FoxDev Studio

A modern IDE and 64-bit runtime for Visual FoxPro 9 applications: the same language, rebuilt on Electron, React and a Rust virtual machine in WebAssembly.

WordPress: Unauthenticated path traversal leading to conditional RCE | 9

An unauthenticated attacker can make `get_page_template()` page-template resolution include a chosen readable local `.php` file outside the active theme directories. If relevant pre-conditions for ...
WordPress/wordpress-develop

Unauthenticated path traversal in page-template resolution leading to conditional RCE · Advisory · WordPress/wordpress-develop · GitHub

GitHub is where people build software. More than 150 million people use GitHub to discover, fork, and contribute to over 420 million projects.

What California is learning from solar panels built over irrigation canals | 5

kqed.org

Attention Required! | Cloudflare

Native apps written in TypeScript and CSS | 4

Example Gea applications and tools — the app gallery used by the simulator, the embedded targets, GeaOS and the Apple targets. - geastack/examples
geastack/examples

GitHub - geastack/examples: Example Gea applications and tools — the app gallery used by the simulator, the embedded targets, GeaOS and the Apple targets. · GitHub

Example Gea applications and tools — the app gallery used by the simulator, the embedded targets, GeaOS and the Apple targets. - geastack/examples

The UV index is not the warm sensation of sunlight on bare skin | 0

blog.asciitweezers.com

The UV index is not the warm sensation of sunlight on bare skin

No Sloptober | 6
When you see this logo on any artwork, whether painting, poetry, or prose, you know that it was made by a human just like you
The Brainmade mark can be attached to any work made mostly by you or your friends, not generative tools like GPT. It’s not anti-AI, it is a positive mark that celebrates human creation. It’s not AI = bad, it’s human = good. There’s something transcendent and magical in knowing a human made the artwork I’m consuming, knowing they tried hard is part of the experience. It doesn’t have to be 100% human made (what would that even MEAN these days?), perhaps 90% human made.
I don’t hate AIs,
I love humans!
no-sloptober.com

No Sloptober

This October 2026 we challenge you to abstain from LLM based tools entirely. Think of this as a fast for your mind! This is not a judgement of others, but a personal challenge to you.

Did OpenAI solve the wrong Navier-Stokes problem? | 8

scientificamerican.com

ERROR: The request could not be satisfied

Markdown in /src | 13

Markdown in /src

htmx.org

</> htmx ~ Markdown in /src

In this essay, Carson Gross argues that Markdown is now an important source artifact for software systems built with LLMs, and that, following the principle of locality, it should live in /src, alongside the code it produces.

OpenAI is well positioned to fast-follow Jev | 40

arcturus-labs.com

Will OpenAI Eat Jev's Lunch? - Arcturus Labs

TypeSafe's Jev is a genuine breakthrough – snap judgments with calibrated probabilities instead of generated text. My bet is OpenAI is already figuring out how to copy it, and then embed it inside its own models where Jev can't follow.

An update on how we confirm your age group on Discord | 6

discord.com

Safer for Teens, Same Discord for Adults

We’re launching a revamped, privacy-focused age assurance solution including methods that won’t require an ID or selfie. Here’s how it works.

MUNI Heritage Weekend in San Francisco | 10

daniel.lawrence.lu

Muni heritage weekend

I went to San Francisco for Muni Heritage Weekend 2026! I stood by the tracks for three hours with my line scan camera, scanning trams.

Unreal Agent | 22
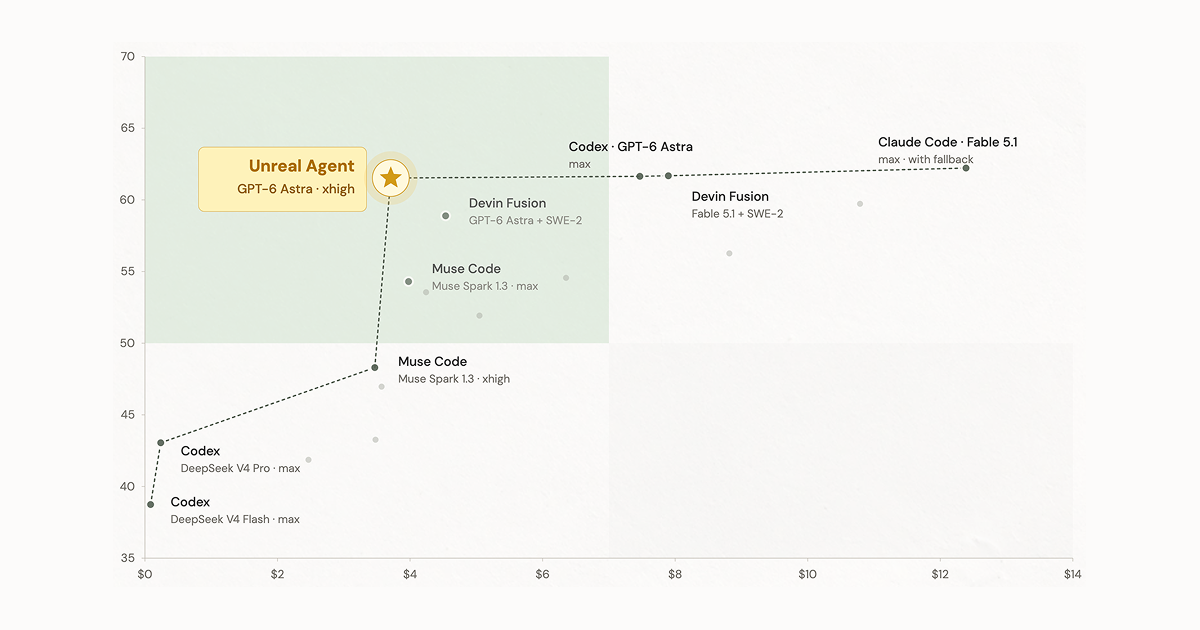
Quality versus cost frontier for coding agents, highlighting Unreal Agent with GPT-6 Astra at xhigh reasoning effort.
unreallabs.ai

Unreal Agent — Unreal Labs

We’re sharing Unreal Agent — an agent harness that delivers up to 40% cost savings compared to Codex on production workloads and coding/science benchmarks, without any negative performance impact.

Show HN: Training a model to identify AI web content from structure alone | 6

Show HN: Training a model to identify AI web content from structure alone

Hey HN! We’re Vincent and Jochen from Sitefire (https://sitefire.ai). We have been working together for years, with backgrounds in RL/optimization at Stanford and software engineering from Technical University Munich (TUM).

With Sitefire (YC W26), we help marketing teams get recommended by AI Search (ChatGPT, Google AI Overviews, AI Mode, Claude, etc.). Our software monitors prompts, sees which web pages get cited, and uses these insights to help marketing teams take action, e.g. create YouTube videos or write the right blog posts.

This means we have a commercial stake in AI-generated web content. And for now, high-information, AI-generated content works great to get cited and recommended in AI Search.

But after talking to hundreds of marketing teams, it became clear that everyone despises AI-generated content (“AI slop”). And yet, everyone still wants to leverage AI to create content. So we asked ourselves: what characterizes AI slop? Can we train a model to identify it from human-generated web pages?

Researchers from the University of Maryland and Google DeepMind already asked this question for fiction. Their paper StoryScope (Russell et al., 2026) showed that you can tell AI-written stories from human ones by their structure alone, without looking at the words.

We ported their pipeline to commercial web pages. Using the Wayback Machine, we collected 2,250 blog posts from 268 B2B company websites that were written before ChatGPT existed. For each blog post, five AI models (GPT-5.4, Claude Sonnet 4.6, Gemini 3 Flash, DeepSeek V3.2, Kimi K2.5) wrote their own version.

Instead of looking at the words, we looked at how each post is built. We had an AI model answer 214 questions about every post, e.g. how hard it pushes its own product, whether it backs up its claims with sources, or whether it quotes a named expert. Then we trained a classifier on these answers.

On blog posts it had never seen before, our classifier told AI-generated and human posts apart with 98% accuracy, getting only 19 of 1,740 wrong.

Why does it work so well? Because all five AI models write in a similar shape. Mapping every AI model’s values for these features, we see they cluster together, while the human values sit apart and spread out much more. Of the 1% most unique blog posts in our data set, 149 are human, only 4 are AI.

So what characterizes AI slop? It tells you the same thing three times. The title already promises what you'll get ("How to Cut Onboarding Time in Half"), the intro lays out what's coming, and the ending says it all again. 77% of the AI posts end by repeating their main point, compared to only 12% of the human posts. We call it the tidy, self-announcing blog post.

Still, each AI model has its own accent. We trained a second classifier to tell which of the five AI models wrote a post, or whether a human did. It picks the right author 79% of the time, where random guessing (1 in 6) would get 17%. Almost all of its mistakes are mix-ups between the AI models, not between human and AI.

The cool thing about structural features is that you can't simply reword your way out of it. We had each AI model rewrite its own posts until, on average, 73% of their original 13-word sequences were gone, and the AI slop classifier still worked just as well.

We're building this into Sitefire: our agents get a structural understanding of text, so the posts they write go deeper and vary the way human writing does.

There's a lot we haven't tested yet, like the myriad of humanizer tools, human rewriting, restructuring a post, or prompting an AI model to explicitly avoid these habits. And our human posts are mostly from 2020 to 2022, while the AI posts were generated in August 2026. Structure can't really tell when a human post was written, but it's still not a same-year comparison.

We published the study with all the figures on arXiv: https://arxiv.org/abs/2609.15369. The code is on GitHub: https://github.com/pulse-energy-eu/slopshape

We're pretty sure your own blog isn't AI slop, is it? We built a checker that runs one of your posts through the ten features from the paper, so you can see for yourself (the full report asks for a work email): https://sitefire.ai/slop-checker.

Think you can tell AI slop from human writing? We also made a little game to see if you can keep up with our model, which gets all five rounds right: https://sitefire.ai/spot-the-slop. [jochenmadler]

Madler, Jochen

[2609.15369] SlopShape: Identifying AI-Generated Commercial Web Content

Abstract page for arXiv paper 2609.15369: SlopShape: Identifying AI-Generated Commercial Web Content

How did AMD Ryzen get 50% faster in two years? | 17

lemire.me

How did AMD Ryzen get 50% faster in two years?

Rabbit Hole: Minimum L-seams | 2
fractalkitty.com

Rabbit Hole: Minimum L-seams

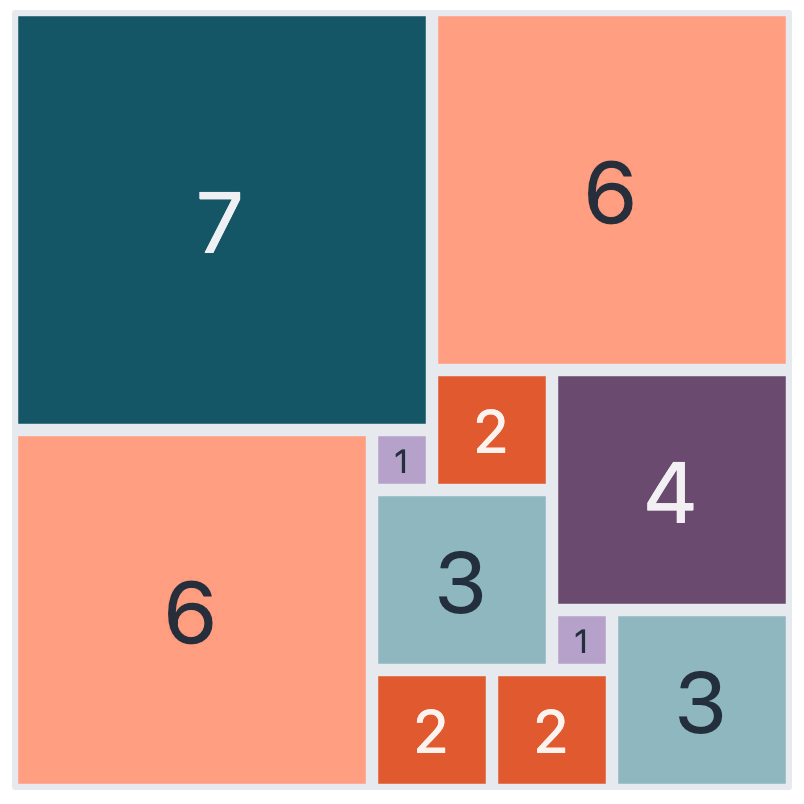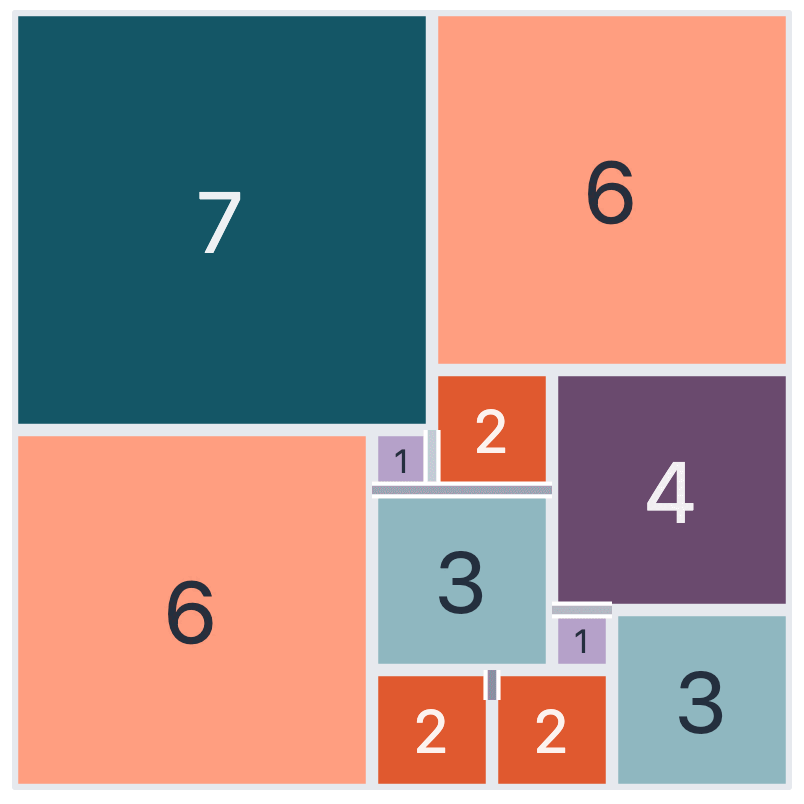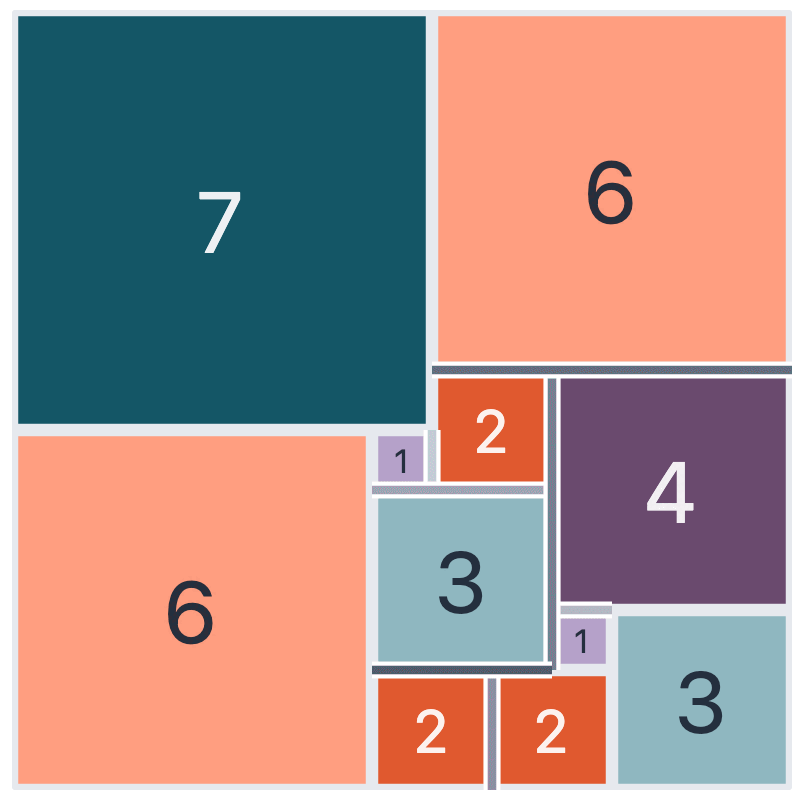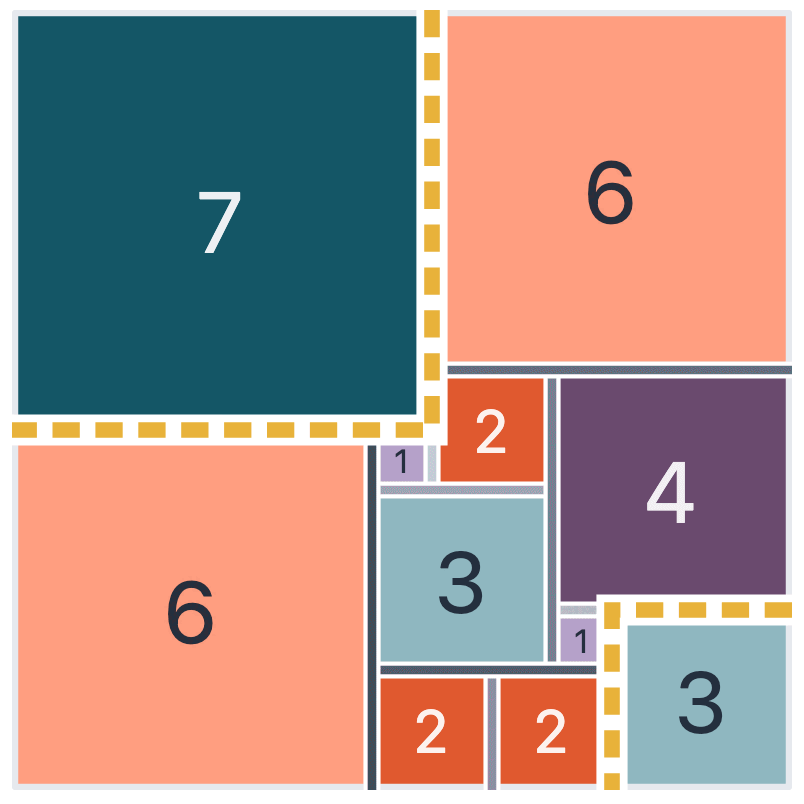
I was trying to write a post about art with squarable numbers, and so I thought quilting a Mrs. Perkins' Quilt might be a nice addition to the exploration. With 1500 words almost ready to hit send, I ended up down a rabbit hole. This post is rather long and

A Faster Shortest Path Algorithm | 4
vals.ai

A Faster Shortest Path Algorithm

Private, domain-specific benchmarks in legal, tax, and finance.

Show HN: JevBench, a reproducible benchmark for typed decision models | 2

Show HN: JevBench, a reproducible benchmark for typed decision models

Hi HN! I built JevBench because Jev kicks ass, and the world deserves to know how the serious open source and fake lookalike projects really perform in comparison.

Jev-class models return bounded choices and probabilities instead of text, and are disruptively faster and cheaper than LLMs, while being similarly intelligent on the text input they operate on.

JevBench allows looking at accuracy, latency and price all at once, in a weighted way - you can even configure the weighting.

A full run asks 534 English decisions. The v1.3 score combines chance-corrected Intelligence, Calibration, Speed and Cost.

Leaderboard right now:

  #1 - Jev            74.4
  #2 - SemIf          73.1
  #3 - djev           73.0
  #4 - Winnow-12B Q8  71.2
  #5 reflex 4B        70.3.
MIT harness, public items, frozen artifacts, scoring code and public per-task outcomes:

https://github.com/fstandhartinger/jevbench

Two no-signup demos:

https://who-is-right.app.mintapis.com

https://is-it-ai-slop.app.mintapis.com

Limitations: English-only; latency from one German server; local/demo latency gets a disclosed ×2 adjustment (+150 ms on my servers) which is an informed assumption; held-out prompts still reach evaluated services; ~1-point gaps can be noise.

Wdyt? [florianstandhar]

Top of the JevBench v1.3.0 leaderboard
benchmarkheaven.com

Jev alternatives & benchmark — JevBench v1.3.0 | Benchmark Heaven

52 Jev-class systems tested on 534 decisions. Jev 1.13.0 leads JevBench v1.3.0 with 74.4; compare open-source, self-hostable and hosted options.

16-bit Intel 8088 chip (c. 1985) | 7

allpoetry.com

Just a moment...

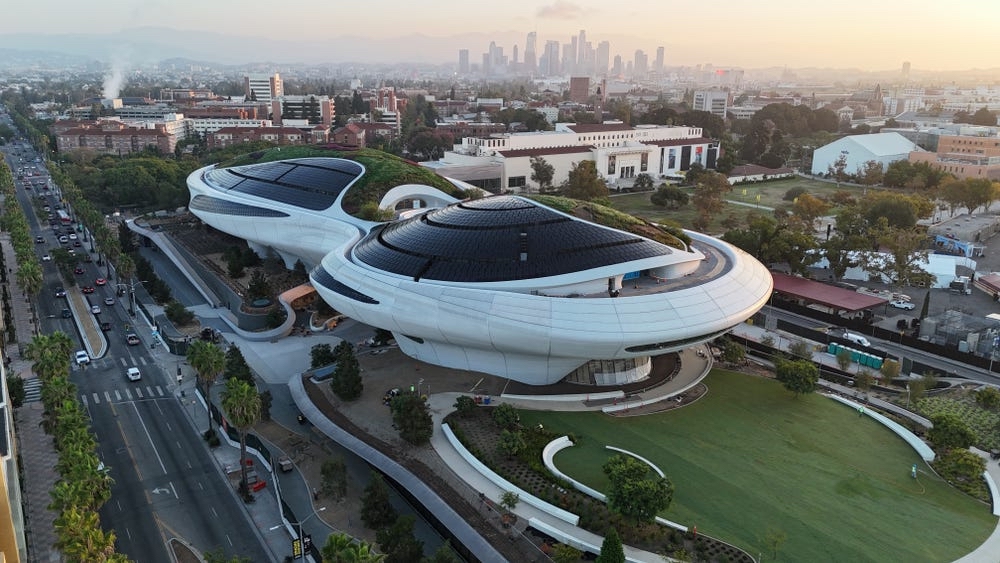
George Lucas Returns to Earth, Bearing Gifts | 5
commonedge.org

George Lucas Returns to Earth, Bearing Gifts – Common Edge

The Lucas Museum of Narrative Art is destined to become a landmark and must-visit destination for Los Angeles visitors.

The JavaScript Midlife Crisis | 4
maroun-baydoun.com

The JavaScript midlife crisis | Maroun Baydoun

Thirty years in, the JavaScript ecosystem would like to see other languages. They're younger, leaner and faster. What could possibly go wrong?

Overreliance on AI contributed to missile strike on Iran school – Pentagon 43

bloomberg.com

Overreliance on AI contributed to missile strike on Iran school – Pentagon

Launch HN: Coverage Cat (YC S22) – Umbrella insurance via your personal agent | 7
Launch HN: Coverage Cat (YC S22) – Umbrella insurance via your personal agent

Hey HN! We’re Max and Gabriel the co-founders of Coverage Cat. We’ve been friends for over a decade, met in college then hung out mostly on the internet. We love building products that help people optimize the crufty corners of their lives. Max is a former Google/Microsoft/Two Sigma PM and Gabriel has been working in startups for over a decade.

We’re building Coverage Cat: a licensed insurance brokerage that helps you compare umbrella and home coverage side by side — with straight pricing, no sold leads, and a real broker on the other end. Our current focus is helping tech folks (think L3-L8) buy umbrella insurance.

Coverage Cat pairs AI-guided intake with a licensed brokerage team, so you can size up coverage, see honest price ranges, and compare real carrier options without handing your details to five agents overnight. Folks who use personal AI agents (think Muse, Instinct, Town, Openclaw, etc.) can drive the same flow through the Agent API/MCP.

We’d love your feedback so please do try it out. Just feed the prompt: “Shop for umbrella insurance with Coverage Cat” to your personal agent and let us know what you think!

If you want to watch a couple of agents navigate the flow before you use it there’s a video here: https://youtu.be/1BUkgAn6s-I

For those who are unfamiliar with this type of coverage, here’s a blurb from one of our insurance agents: “Umbrella liability insurance is a policy that provides additional coverage above the limits of existing auto, homeowners, renters, or landlord policies. It kicks in after the underlying policy limits are exhausted and may also cover personal injury claims like libel, slander, or defamation that standard policies often exclude. Policies typically start at $1 million in additional liability coverage and can protect you, your spouse, dependents, and even pets in your household.”

Buying insurance online is a miserable experience. You fill out a bunch of forms that say they’re going to give you quotes. Most don’t and then you end up with tons of unwanted phone calls and spam. Even if you wade through the muck, you’ll often still end up with sub-optimal prices and coverage because of a lack of market transparency and poorly-aligned advisory incentives.

We came to this problem because Max is a classic personal finance obsessive. He's the type of person that needs to know that he has the best possible price for something (everyone has one friend with the patience for a two hour phone call with the bank for some $10 fee) or that his insurance coverage is as tailored to his risk profile as the market will allow. He actually reads insurance policies end to end.

Years ago, when he shopped for his homeowners insurance it took him 10+ phone calls and dozens of online form fills to find the right deal. He also suffered tons of collateral damage in the process: websites sold his information to dozens of agents who proceeded to call, text, and email him a spam hoard that grows to this day.

After this painful search made us aware of the problem, we also spent a lot of time doing user research with wealthy-ish tech employees to see if they felt the same way. They did, and also complained that they 1) often felt like they'd left money on the table, 2) didn’t really understand their coverages, and 3) that brokers were slow, hard to communicate with, and unreliable.

To solve the problem, we set out to build Coverage Cat. Our approach has three major components:

First, we work really really hard to find and partner with insurance carriers that offer high-quality, competitively-priced products. We've also taken time to identify insurers that work on a direct-to-consumer basis or transparently list their prices online so we can make our customers aware of all the options available to them. We get paid commission when we match users to great insurance deals, but we still show and recommend folks deals that we don't make money on when they're accessible and will always recommend users buy what's best for their personal financial situation. Our goal is to meaningfully improve price transparency so consumers (and their AI agents) can make informed coverage decisions and not get nickel-and-dimed!

Second, we automate every possible part of the insurance process. Some forms, portals, & approvals still need human review due to regulatory constraints, but if it's not restricted, we're automating it. LLMs have given our small team tremendous leverage and enabled us to tackle problems at a scale that would've been unfathomable five years ago.

Finally, we build for agents first (a remix of the more classic adage, build for developers/APIs). We've always been big believers that personal finance would be the killer use-case for the AI revolution and have done our best to position ourselves to surf the wave. As personal assistants have started to explode onto the mainstream (think Muse, Instinct, Town, Codex, CC etc.) we've ensured our shopping and comparison process works via API/MCP so agents can present their users with all the information they need to make a good decision and transform a miserable shopping experience into a delightful one.

Coverage Cat is an unusual business because, while we also help folks find homeowners insurance in California and Texas, our main focus is on umbrella insurance. Most brokerages only sell umbrella coverage as a customer retention product, but it makes them almost no money. We focus on it as our core business because: 1) it's one piece of the insurance puzzle that many people in tech overlook and/or are confused about even though it can have a huge impact on their financial well-being. 2) Existing online tools and brokerages broadly don't make it easy to comparison shop for. 3) It was, for us, the most technically feasible candidate for automation given startup resource constraints.

Insofar as we know Coverage Cat is the first instance of a tool/portal that allows AI agents to complete most of the comparison and shopping steps required to allow people to buy insurance.

Also happy to answer any questions about the product, the problem space, and even some insurance questions (Max is a licensed agent) where regulation permits. Cheers! [botacode]

coveragecat.com

Coverage Cat | AI-native insurance brokerage

Coverage Cat is an AI-native insurance broker for high-earning households. Compare home, umbrella, auto, and renters options online, or integrate the Coverage Cat Agent API.

Apple has added persistent 'ads' to iOS, and it's driving users crazy | 79
A man looking frustrated at his mobile phone
techradar.com

‘I wish Apple would just stop that crap': Apple has added persistent ‘ads’ to iOS, and it’s driving users crazy | TechRadar

Way to cheapen the experience, Apple

There's a high chance of devices being sold with GrapheneOS preinstalled in 2027 | 14

grapheneos.social

GrapheneOS: "@tranquil_cassowary@infosec.exchange @ocelot221@m…" - GrapheneOS Mastodon

@tranquil_cassowary@infosec.exchange @ocelot221@mastodon.social @mhoye@cosocial.ca @mulchmaxxing@blahaj.zone There's a high chance of devices being sold with it preinstalled in 2027 but probably not for the initial launch.